
将变量分解为R中的两个新变量
将变量分解为R中的两个新变量
提问于 2021-03-09 13:29:03
所以我正在使用R工作室中来自ISwR包的数据集bcmort。该数据集包含了丹麦和其他地区乳腺癌死亡的信息,然后才开始进行筛查。
我想要做的是把队列变量(由4个层次组成)分成变量‘周期’和‘区域’。
知道我会怎么做吗?
提前感谢
编辑:我认为,如果显示队列的级别,可能会有所帮助:
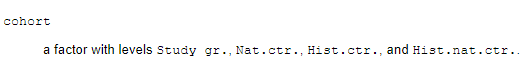
四个层次是:研究组、国家研究组、历史研究小组、历史研究小组。
回答 1
Stack Overflow用户
回答已采纳
发布于 2021-03-09 17:54:08
不知道您想要的输出是什么样子,下面是一个使用dplyr和stringr函数的通用解决方案。我可以从这四个因素级别猜出您希望如何构造新变量Area和Period,但我不知道我的方法是否是您想要的。
从我的快速检查中,我猜您的Area变量是基于Cohort是否是"national“的。我猜想Period变量是基于Cohort是否是“历史的”。在本例中,我将使用来自str_detect包的stringr来检测队列值中的模式。我将使用mutate创建新列。
library(ISwR)
library(dplyr)
library(stringr)

bcmort %>%
  mutate(Period = if_else(str_detect(cohort, "Hist"), "Historical", "Not historical")) %>%
  mutate(Area = if_else(str_detect(cohort, "Nat|nat"), "National", "Not national"))

     age        cohort bc.deaths    p.yr         Period         Area
1  50-54     Study gr.         9   64144 Not historical Not national
2  55-59     Study gr.        34   92734 Not historical Not national
3  60-64     Study gr.        43   83510 Not historical Not national
4  65-69     Study gr.        53   87408 Not historical Not national
5  70-74     Study gr.        56   77427 Not historical Not national
6  75-79     Study gr.        28   25600 Not historical Not national
7  50-54      Nat.ctr.        89  767111 Not historical     National
8  55-59      Nat.ctr.       434 1067778 Not historical     National
9  60-64      Nat.ctr.       516  906943 Not historical     National
10 65-69      Nat.ctr.       535  826254 Not historical     National
11 70-74      Nat.ctr.       545  635385 Not historical     National
12 75-79      Nat.ctr.       214  192946 Not historical     National
13 50-54     Hist.ctr.        22   57669     Historical Not national
14 55-59     Hist.ctr.        45  113143     Historical Not national
15 60-64     Hist.ctr.        82  139065     Historical Not national
16 65-69     Hist.ctr.       104  155697     Historical Not national
17 70-74     Hist.ctr.       128  128454     Historical Not national
18 75-79     Hist.ctr.        57   40196     Historical Not national
19 50-54 Hist.nat.ctr.       104  577528     Historical     National
20 55-59 Hist.nat.ctr.       443  931245     Historical     National
21 60-64 Hist.nat.ctr.       485  916923     Historical     National
22 65-69 Hist.nat.ctr.       491  838476     Historical     National
23 70-74 Hist.nat.ctr.       418  608008     Historical     National
24 75-79 Hist.nat.ctr.       182  182824     Historical     National
如果我猜错了,那么您可以适应您想要的输出。
页面原文内容由Stack Overflow提供。腾讯云小微IT领域专用引擎提供翻译支持
原文链接:
https://stackoverflow.com/questions/66547836
复制相关文章
相似问题
腾讯云开发者

Copyright © 2013 - 2026 Tencent Cloud. All Rights Reserved. 腾讯云 版权所有
深圳市腾讯计算机系统有限公司 ICP备案/许可证号:粤B2-20090059  粤公网安备44030502008569号
腾讯云计算(北京)有限责任公司 京ICP证150476号 | 京ICP备11018762号